Configuring a RAG
A RAG deployment grounds model answers in your own documents. Once it's deployed, you configure it from its page in the portal — which models it uses and who can access it. Its vector database is provisioned and managed for you; there's nothing to set up there.
(For the document, retrieval, and chat APIs, see RAG; for programmatic access, see API Keys.)
Description
Agents and models read the RAG's description to decide when to search this knowledge base, so it should name the domain it covers and what is in it — for example: "Scientific knowledge base containing eleven papers on efficient large language model inference." Set it when you create the RAG, or later with Edit description at the top of the RAG's page.
Models
Under Settings, choose the models the RAG uses. Each can be any model on the platform — in-cluster or external:
- Embedding model — required; turns documents and queries into vectors.
- Completion model — optional; generates answers from retrieved context.
- Reranker model — optional; reorders retrieved chunks for relevance.
- OCR model — optional; reads text from images and scanned PDFs. Only models explicitly typed OCR can be selected (currently dots.OCR).
A model only works while it is running. A stopped model is still listed so you can see it exists, but it is marked (stopped) and cannot be selected — start it from the Models page first, then pick it here. External models are always available.
When you create a RAG, each model is filled in from the platform default. A field is left empty instead when its platform default is no longer usable for that role — the model was deleted, is not available to you, is not of the role's type (only the OCR model field checks the type), or is stopped — and you can choose a model yourself. If every model listed for a required role is stopped, the form says so, and Create stays disabled until an embedding model is running.
On an existing RAG, a model that has stopped since it was configured stays selected but is marked (stopped). Start it again from the Models page, or pick another model — a stopped model fails queries that reach it.
If you leave Reranker model empty, the RAG uses its normal search ranking and skips reranking. To rerank retrieved chunks, choose a reranker model and use a reranker retrieval config. Plain cosine and BM25 hybrid configs do not rerank, even when a model is selected.
Behavior
Also under Settings, tune how the RAG retrieves and handles documents:
- Smart temporal search — time-aware queries ("latest policy", "what changed last month") automatically prioritize the most time-relevant documents.
- Require group for retrieval — only return results when the query names a document group, keeping every query scoped to a group.
- Use PDF OCR by default — run OCR on PDFs and images at upload (requires an OCR model).
- Auto-delete files without a group — discard any uploaded file not assigned to a group.
- Reranker top N — how many retrieved chunks the reranker considers. Only used with a reranker retrieval config and a selected Reranker model.
- Reranker batch size — how many chunks the reranker scores at once. Only used with a reranker retrieval config and a selected Reranker model.
The defaults suit most deployments; adjust these only for specific needs.
Data sources
A data source connects the RAG to a store where you already keep your files. The RAG reads the files, indexes them, and reads the store again later to pick up changes.
Portal
Open the RAG's Files tab and select Add source.
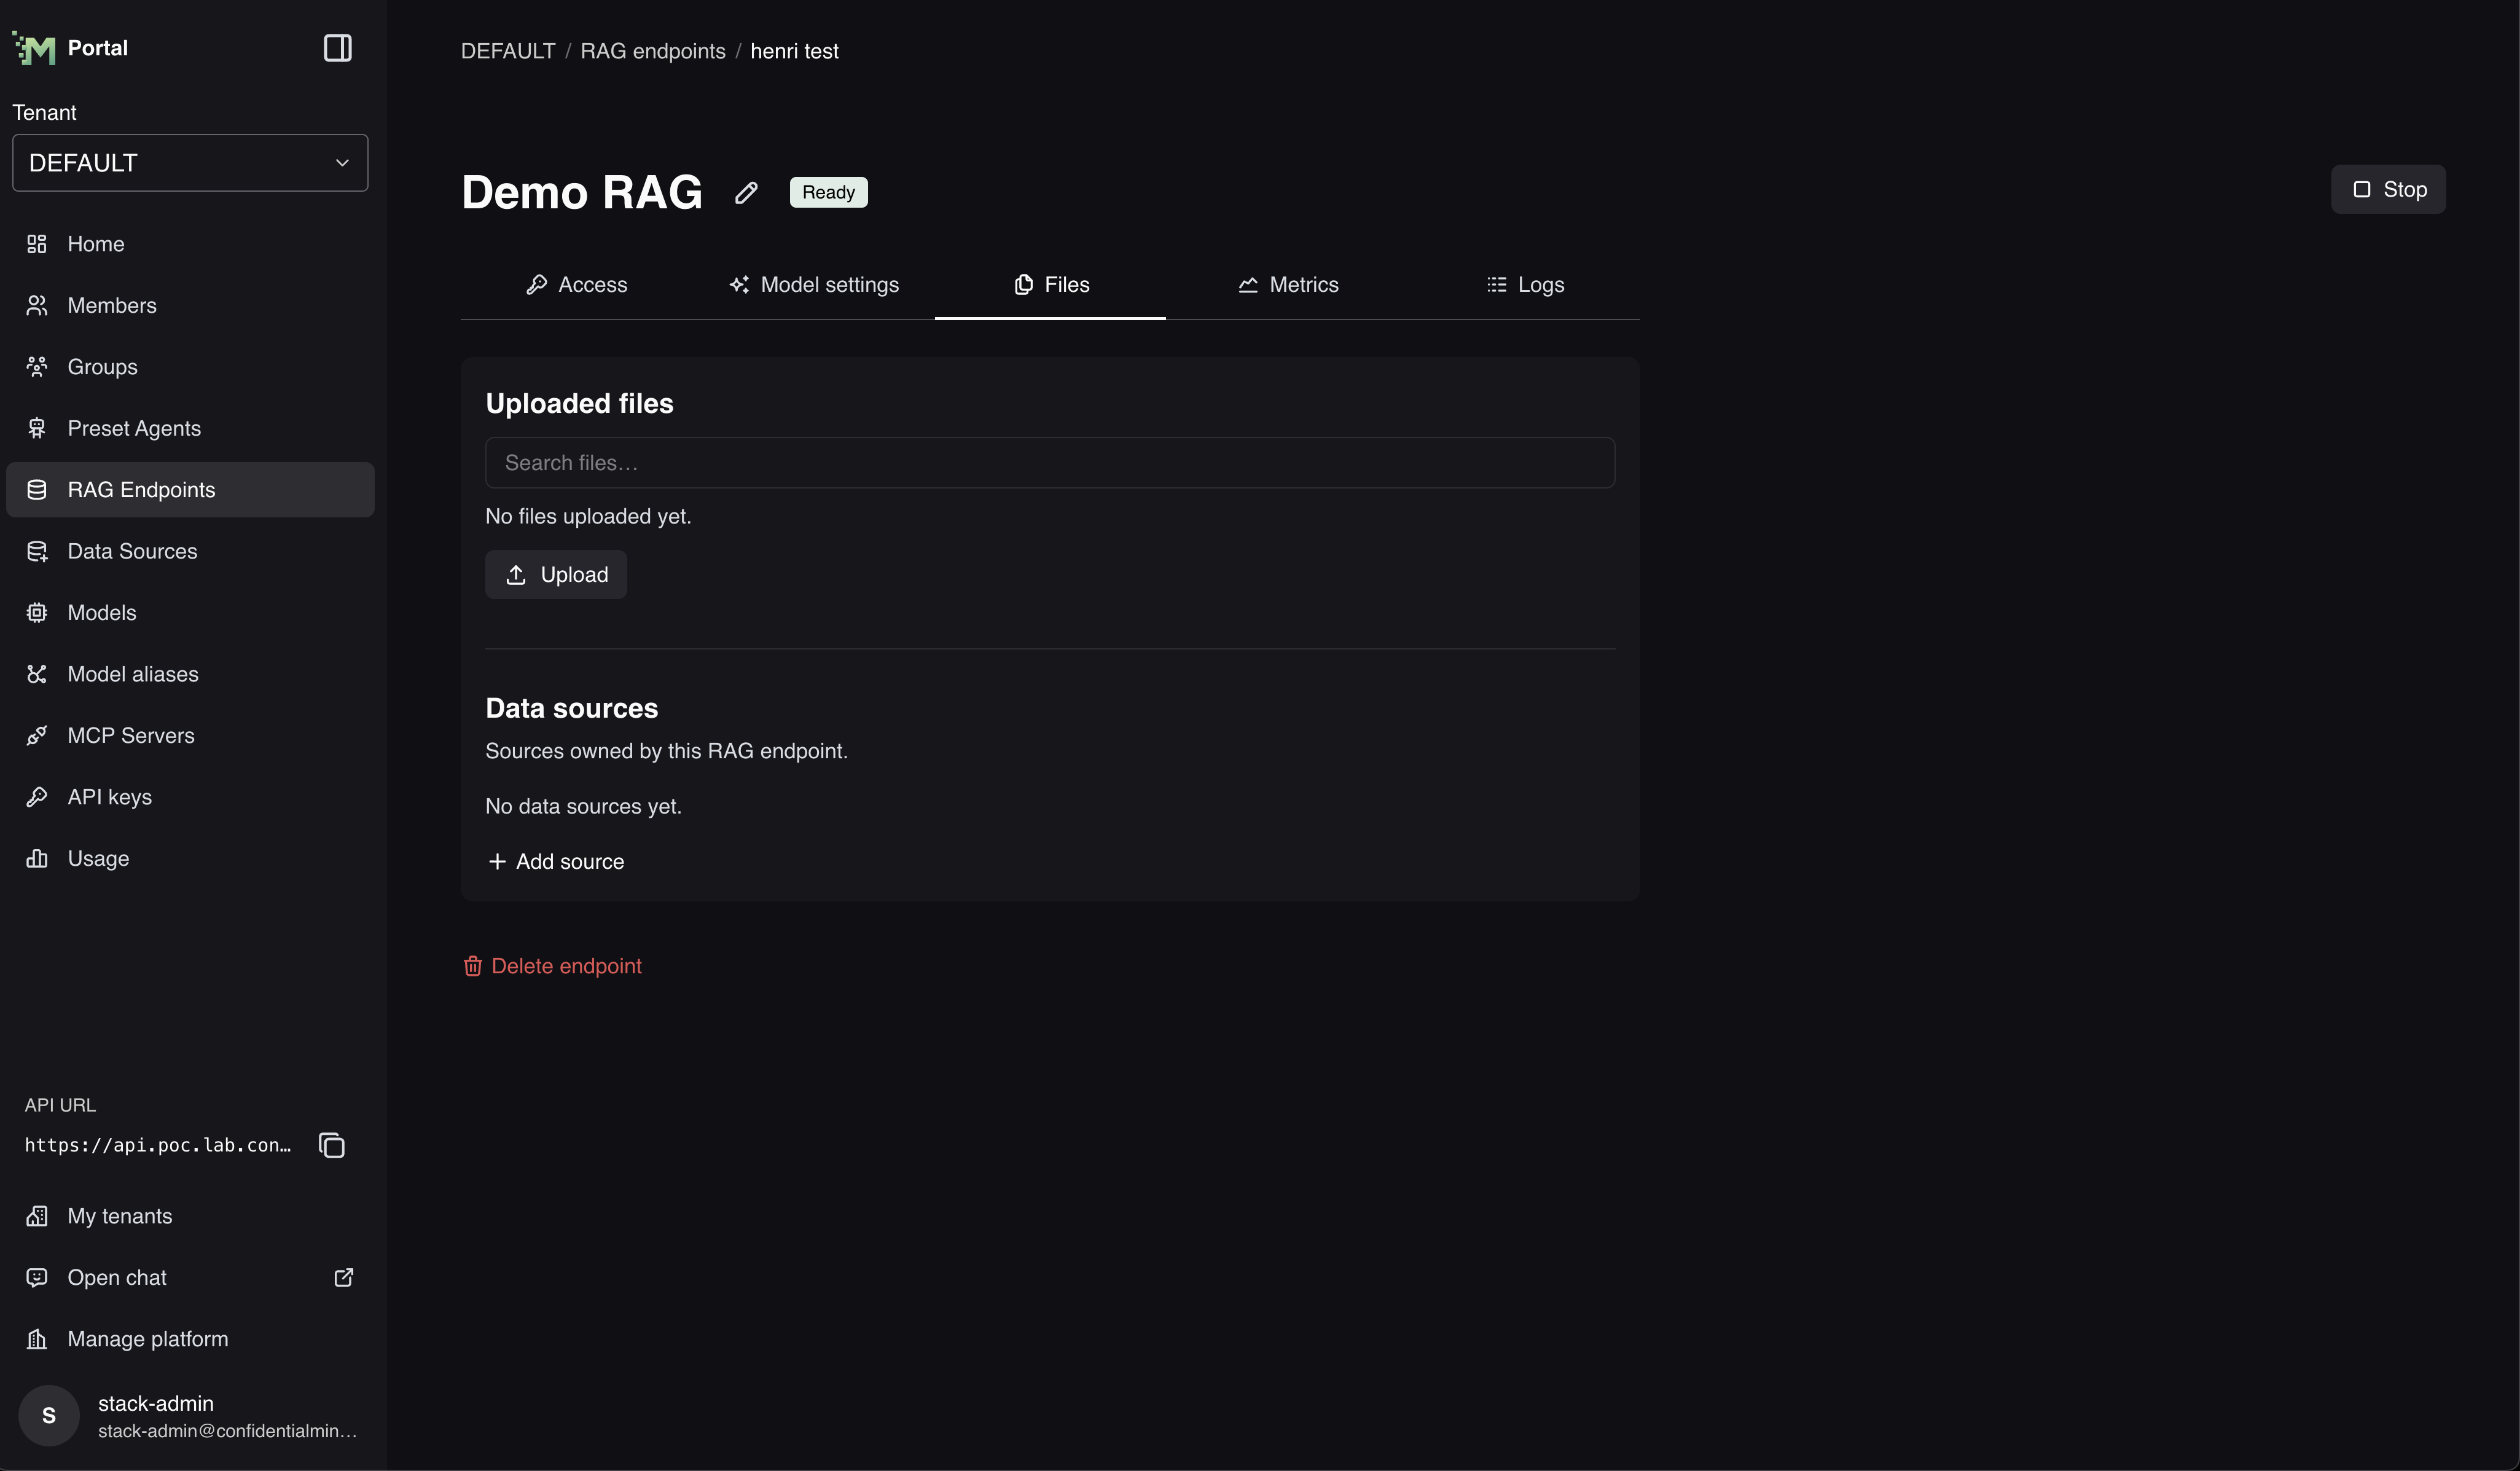
Choose the Provider first — the fields under it change with your choice:
- S3 — Endpoint, Region, Bucket, Access key ID, and Secret access key.
- Azure Blob Storage — Connection string and Container. The account endpoint is taken from the connection string, so you do not type it.
- SMB file share — Server, Share, Port, Require SMB encryption, Username, Password, and Domain. The domain is optional; leave it blank for an account that exists only on the file server.
Every provider also asks for:
- Name — how the source is listed in the portal.
- Prefix — optional. Read only the files whose name starts with this text. Leave it empty to read the whole bucket, container, or share.
- Sync interval — how often the RAG reads the store again. Choose Manual, 10 minutes, 1 hour, 1 day, 7 days, or a custom interval of at least 10 minutes.
Once the source is added, select it in the list to see its settings. An S3 source shows its Endpoint and Bucket; an Azure source shows its Account endpoint and Container.
Access
Portal
Open the RAG's Users tab. It has two sections:
- Administrators — edit, start, stop and delete the endpoint, and manage its data sources.
- Viewers — read the endpoint's configuration and data sources, without changing anything.
Select Add administrator or Add viewer, search by name or email, tick the users and groups you want, then select Add. Each row has a remove button. See Access to one resource for the full steps.
The RAG's Access tab holds its API URL and the calling examples.
Updates
A RAG keeps itself on the platform's recommended version automatically — nothing to do to stay current.