Deploying a model
Prerequisites
- Model deployment privileges
- Enough GPU VRAM
- A model from Hugging Face
- Some models require the user to sign an agreement to prevent misuse. In these cases, you will need a Huggingface account and token. Documentation for creating access tokens here: https://huggingface.co/docs/hub/en/security-tokens
- Example:
meta-llama/Llama-3.1-8Brequires signing a community license agreement.
Portal
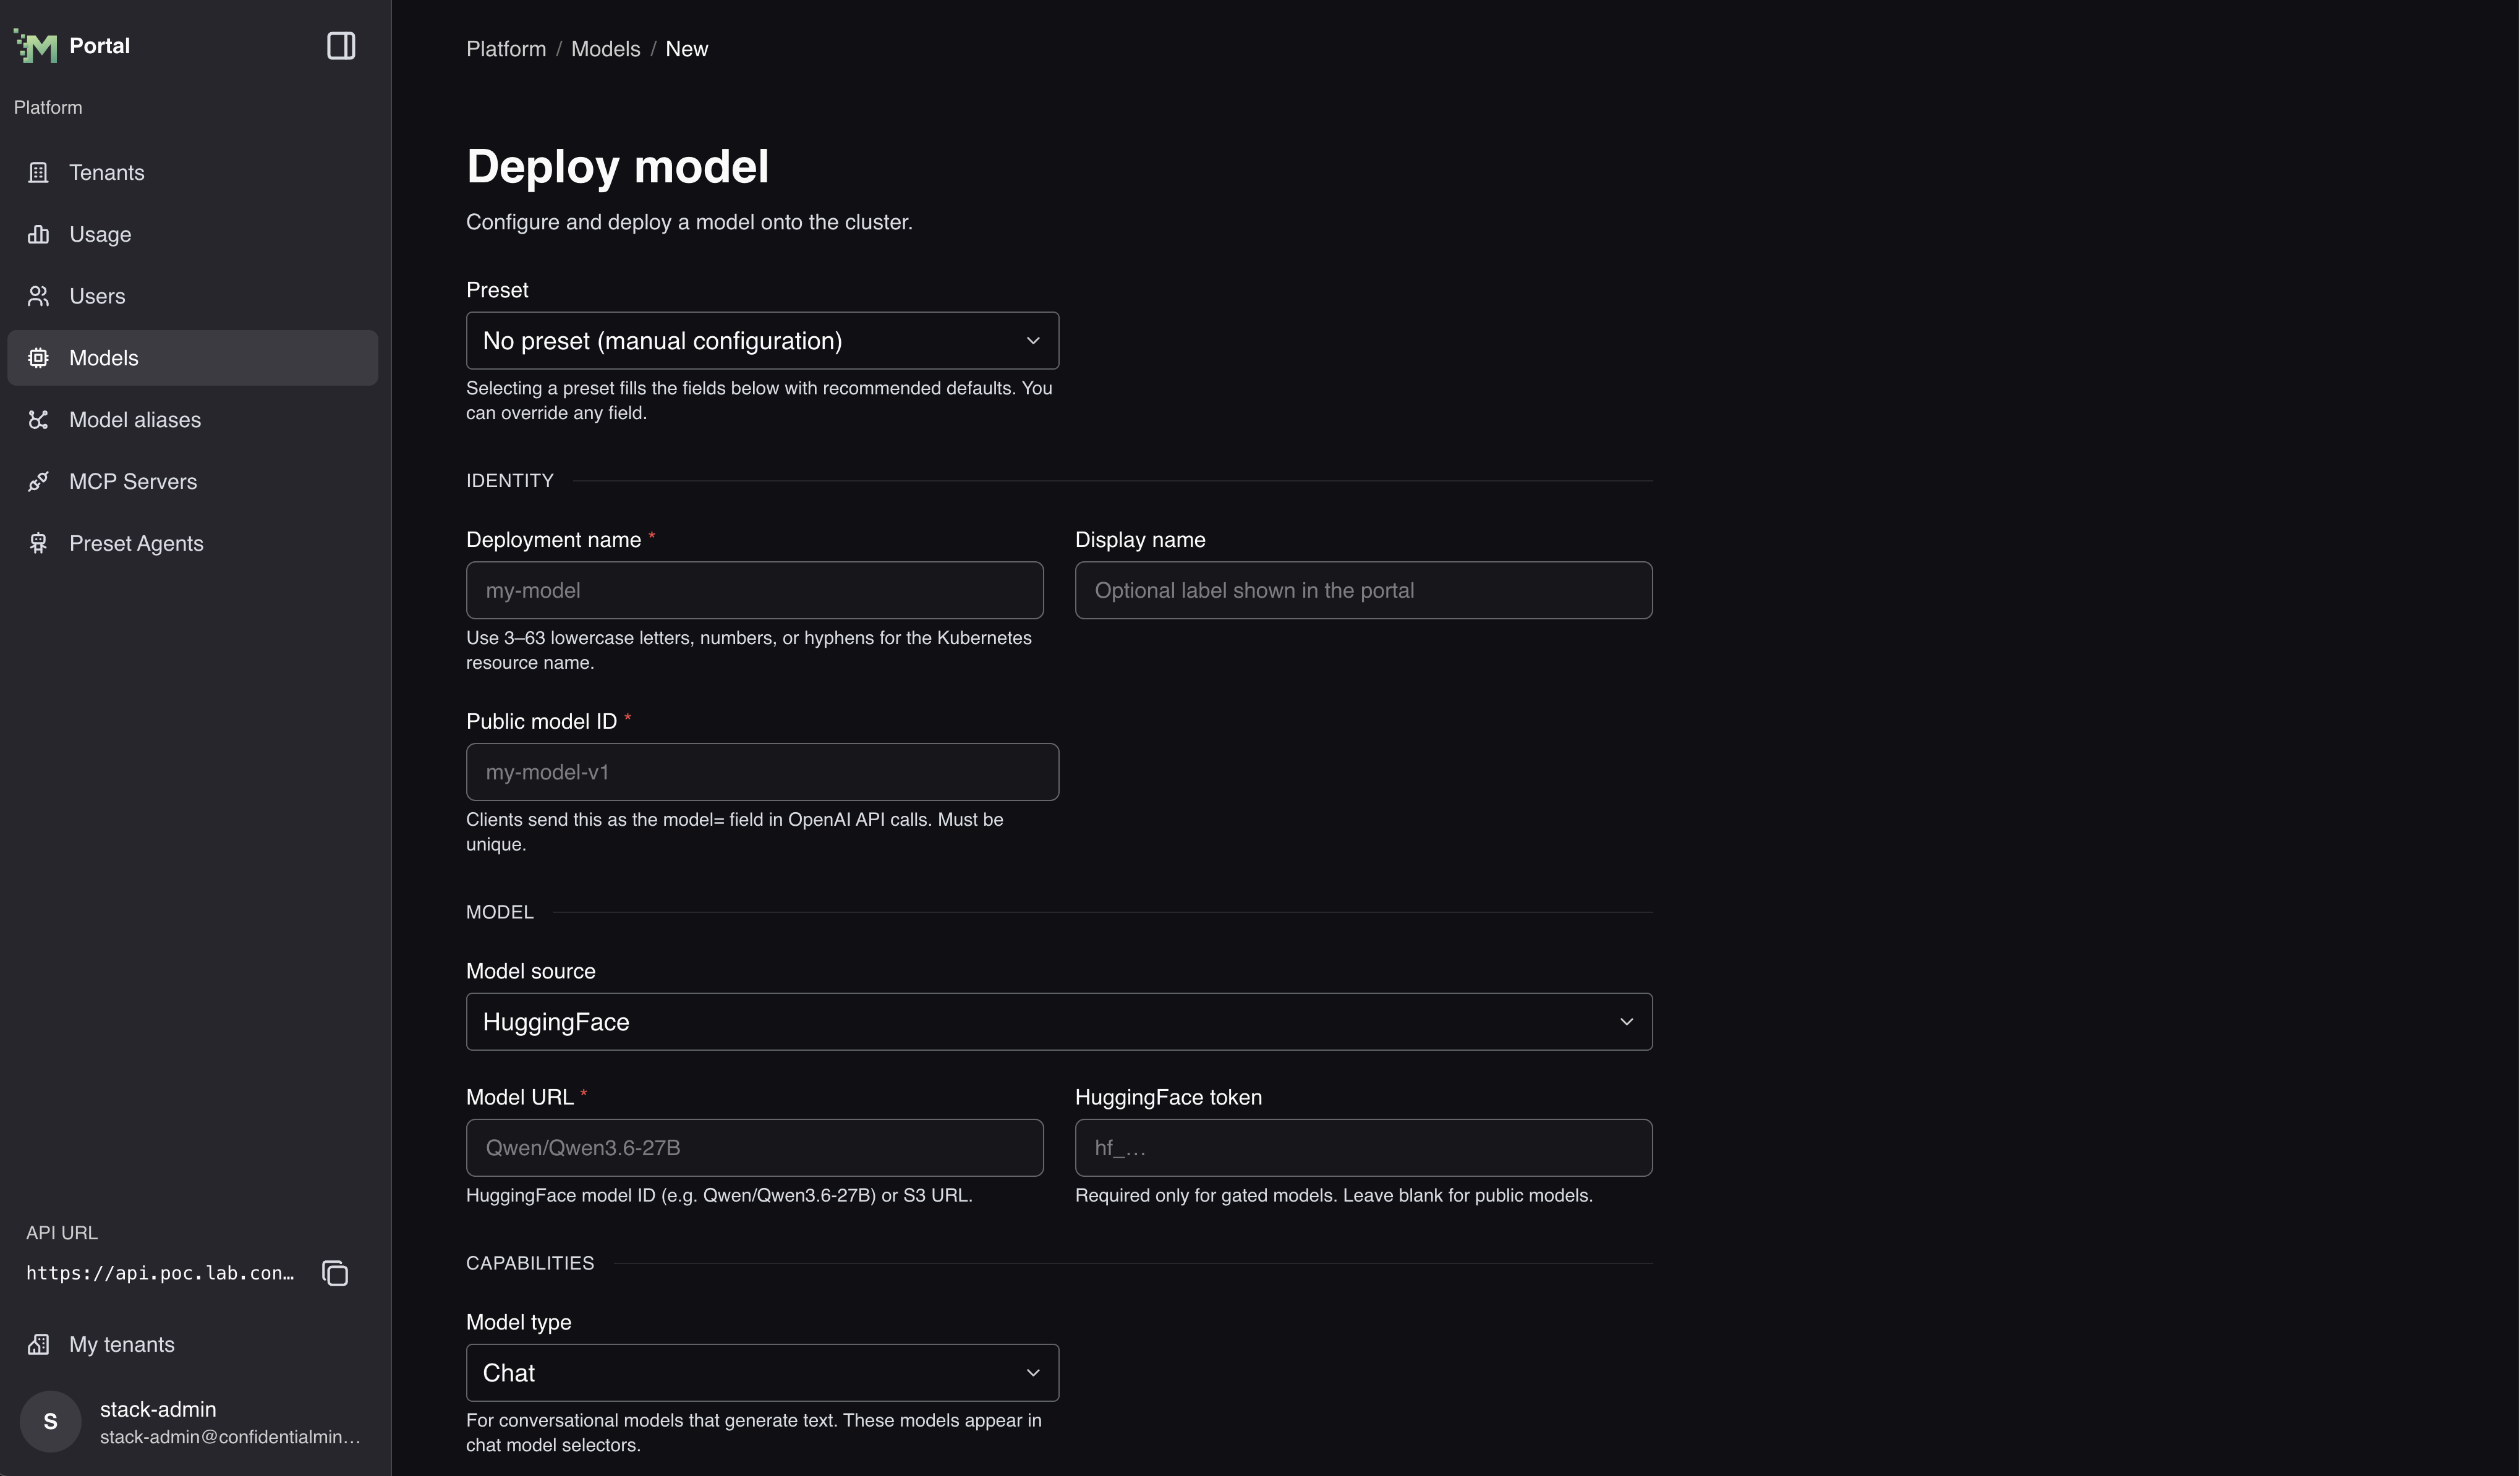
For the Qwen3-0.6B example below, use these portal controls:
- Open Manage platform, then Models, and select Deploy model.
- Keep Preset set to No preset (manual configuration) and Model source set to HuggingFace.
- Enter
Qwen/Qwen3-0.6Bunder Model URL, then fill in Resource name and a unique API model id. - Choose a Node and GPUs with enough free memory. For gated models, enter a HuggingFace token.
- Select Deploy and follow the deployment status. Open Logs to check startup progress.
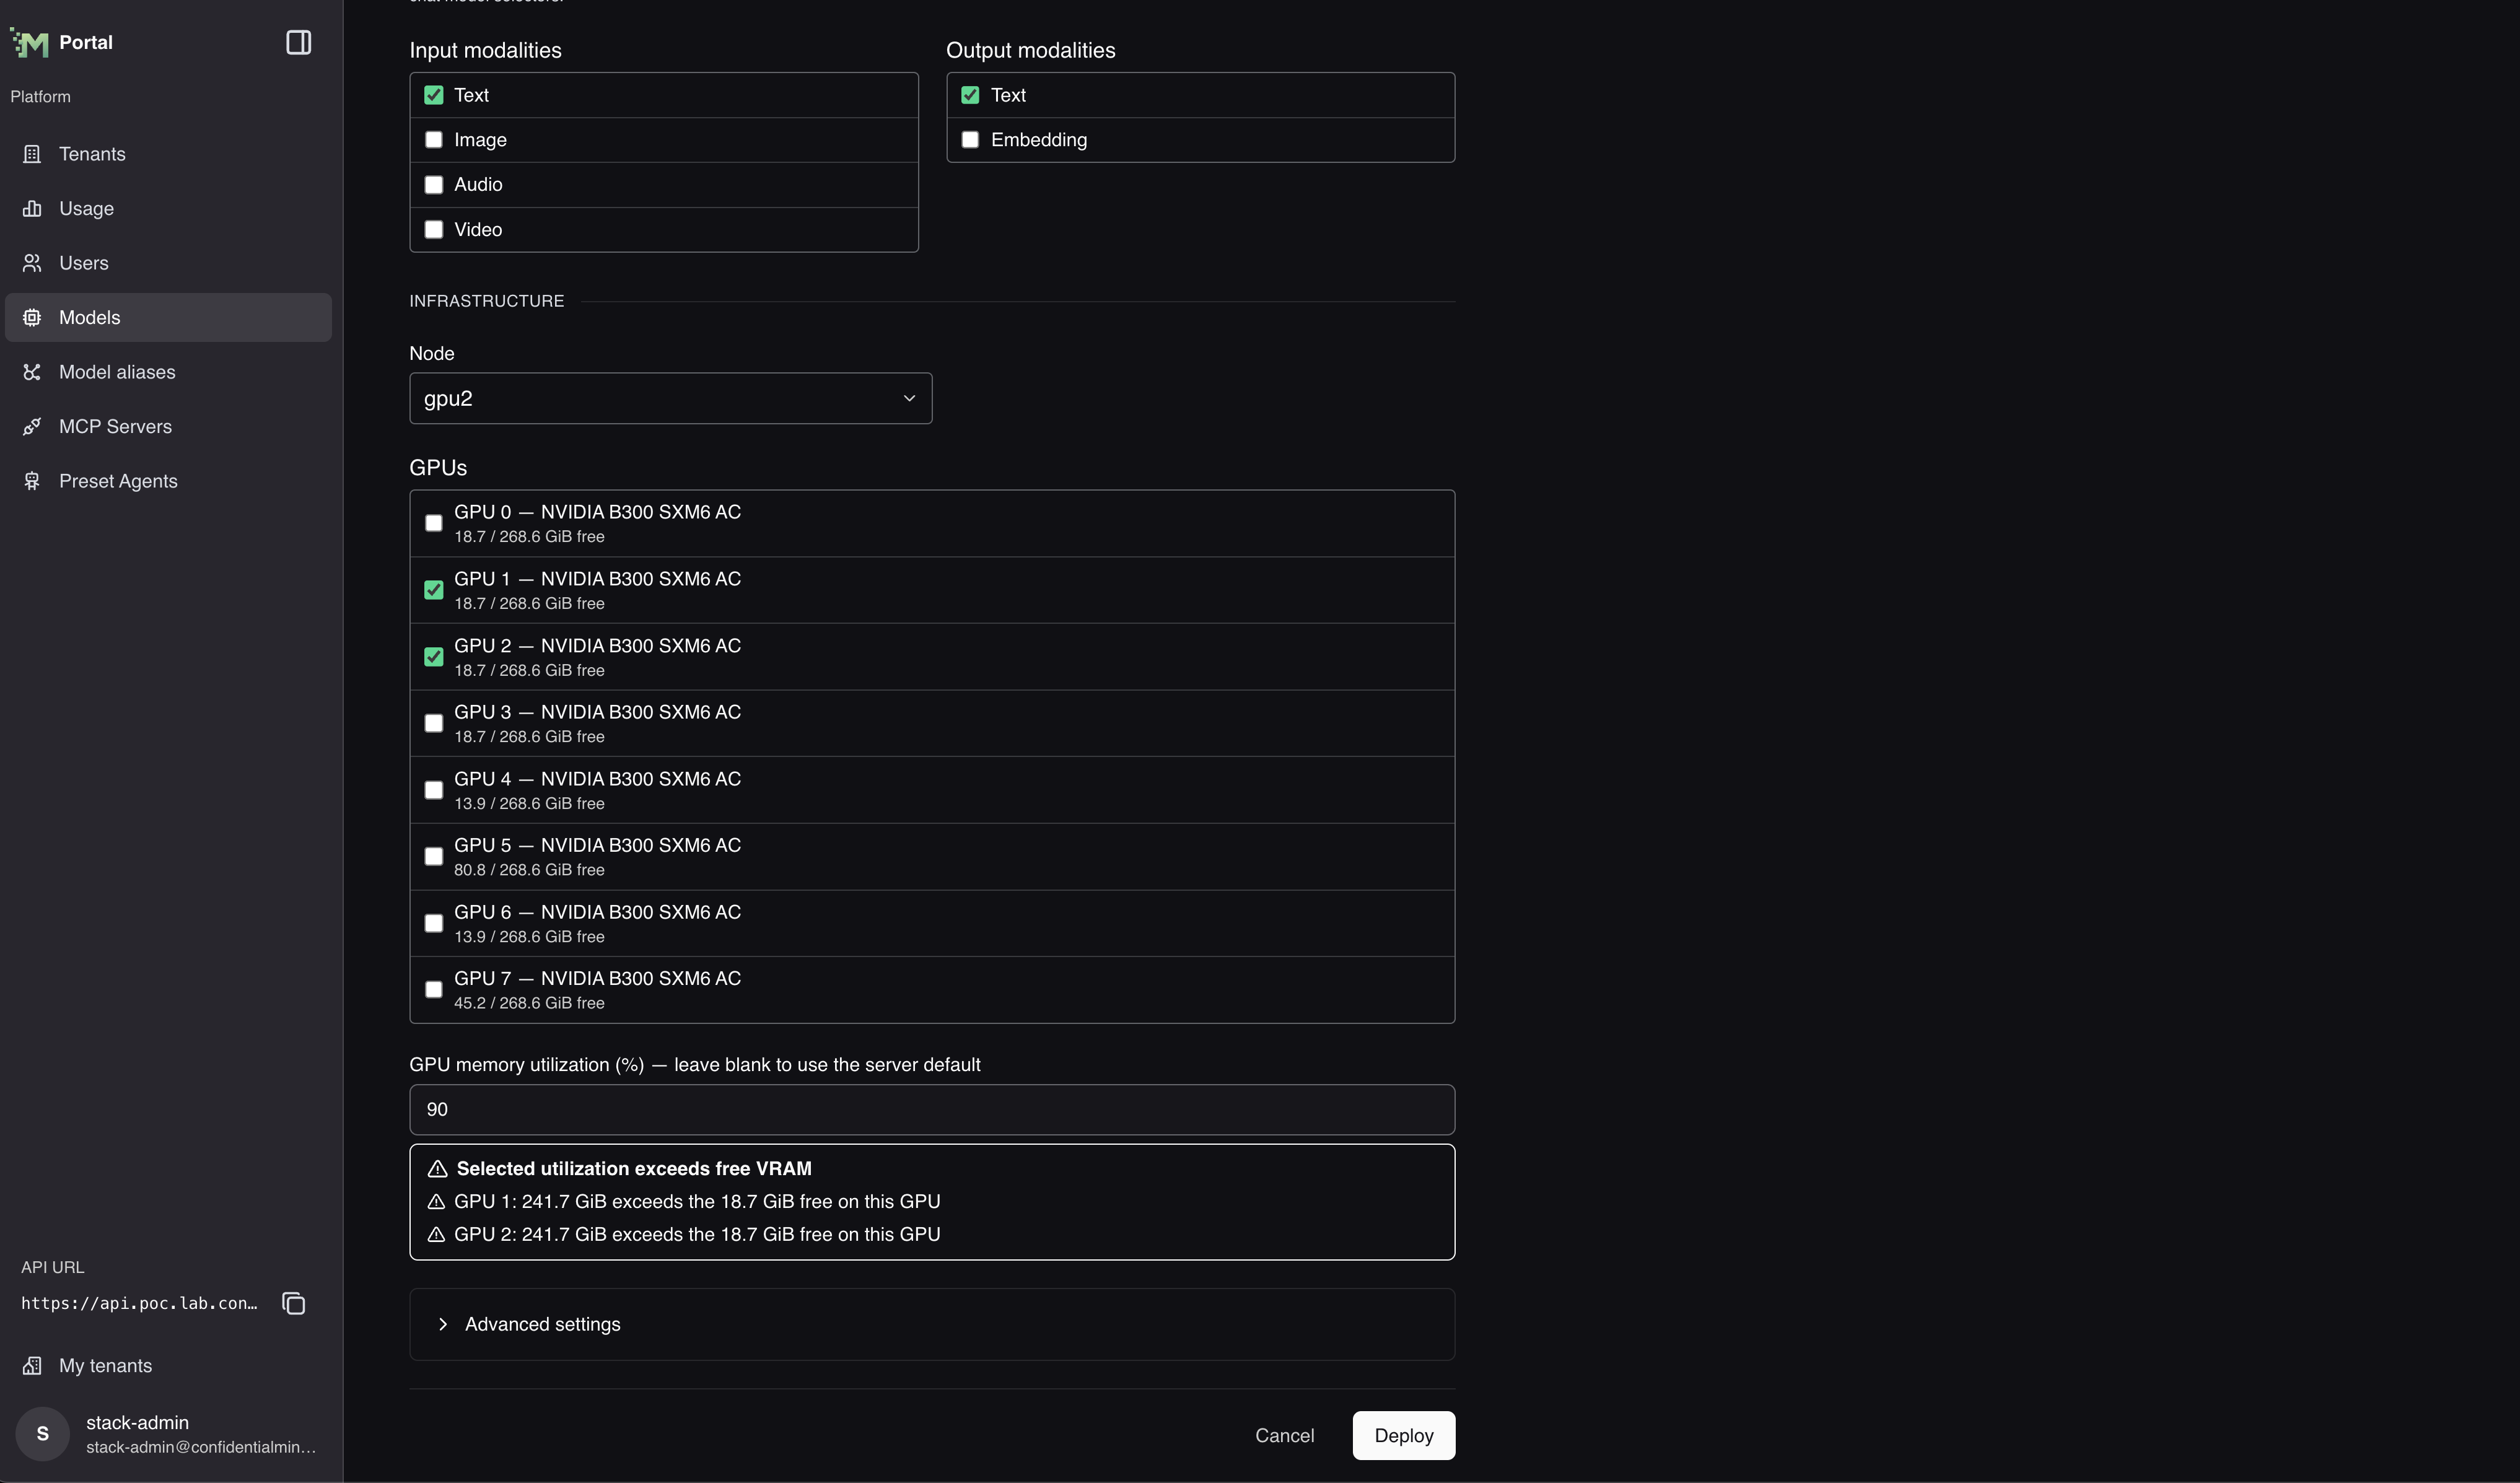
Under Advanced settings, Inference server image takes a complete image reference.
Enter one inference-server argument per line under Arguments.
Use --trust-remote-code only when the model requires it and you trust its code.
Deploying Whisper Large v3
The platform includes a Whisper Large v3 preset for speech-to-text deployments.
- Open
Modelsand selectDeploy model. In the portal,Modelsis under Manage platform. - Select
Whisper Large v3under Preset. - Choose where the preset's model weights come from:
- On a connected cluster, keep
HuggingFace. The preset supplies the model URL. - On an air-gapped cluster, select
Pre-staged local pathand enter the directory that contains the same CTranslate2 Whisper weights. The directory must exist under the configured model cache root on every node where the deployment can run.
- On a connected cluster, keep
- Keep the model type and modalities supplied by the preset. Select
No presetif you need to configure a different model. - Change the resource name, display name, or API model id if needed.
- Select a node and a GPU with at least 4.5 GiB of free VRAM for the default GPU build.
- Select
Deploy modeland wait for the status to becomeDeployed.
The platform manages this preset's runtime image, arguments, environment, tracing, and memory configuration. Those settings are not available on the form. Node and GPU placement remain available.
After the deployment is ready, send audio files to POST /v1/audio/transcriptions. See Model Gateway for the request format.
This model always answers with JSON (json, text or verbose_json) and does not produce the subtitle formats srt and vtt.
Stopping and starting a deployment
Platform administrators can stop an operator-managed model deployment without deleting it:
- Open
Modelsand select the deployment. - Select Stop at the top right of the page.
- Wait for the automatically updating status to change to
Stopped.
Stopping removes the model's serving workload and makes its endpoint unavailable. The deployment configuration and cached model weights remain available for restart.
Stopping an embedding model also stops tokenizer delivery. A running RAG endpoint keeps the tokenizer copy it downloaded at startup. A RAG endpoint that restarts while the model is stopped waits for it and cannot become ready. Start the model before restarting or updating RAG endpoints that use it. See Configuring a RAG.
Replacing an embedding model is different from stopping it. If you delete an embedding model and deploy a different model under the same public model ID, RAG endpoints that indexed documents with the old model cannot become ready again, even after a restart. Their stored documents can only be read by the model that made them. See Configuring a RAG.
Deleting a model also changes the state of the RAG endpoints that use it. An endpoint that uses it as its embedding model shows Error, even if it was answering searches until then, because it can no longer index or search its documents. An endpoint that uses it for generation, reranking or OCR shows Degraded and keeps answering searches. Each endpoint's page names the model it is missing. Deploy a model with the same API model id, and the endpoints pick it up on their own. For an embedding model it must be the same model as before. See Configuring a RAG.
To make the model available again, open its detail page and select Start at the top right. Its status updates as the model starts and returns to Deployed when the endpoint is ready.
A stopped deployment is hidden on the Models page. Select Show stopped models above the list to see it, then open it and select Start. If every deployment is stopped, the list says so and points you to the same setting.
These controls are not available in tenant model views and do not apply to external model connections.
Presets with a platform-managed engine
Some presets use runtime configuration supplied by the platform. The preset fixes the model type and modalities. Keep the preset's Hugging Face source on a connected cluster, or select a pre-staged local path for the same model on an air-gapped cluster. Select No preset (manual configuration) to configure a different model.
For a preset with a platform-managed engine, the portal hides the inference image, arguments, environment variables, and GPU memory utilization, along with the tracing control. The platform sets those values. You can still change the deployment identity, Hugging Face credentials when required, node, and GPU placement.
Deploying on a Tenstorrent node
Ask your platform administrator to enable Tenstorrent support. This includes the bundled Tenstorrent vLLM serving runtime. The platform selects the runtime when you choose a Tenstorrent node.
Choose a model supported by the installed Tenstorrent runtime and hardware. Support in another vendor's runtime does not guarantee support on Tenstorrent.
- Open Manage platform, then Models, and select Deploy model.
- Keep Preset set to No preset (manual configuration).
- Enter the model source, resource name, API model id, and model capabilities.
- Under Infrastructure, select the Tenstorrent node.
- Complete any required fields and select Deploy.
When you select a node whose accelerators are all Tenstorrent devices:
- The individual GPUs selector and GPU memory utilization setting are hidden. The runtime controls device allocation.
- Advanced settings are hidden. The platform manages the inference server image, arguments, environment variables, and tracing configuration.
- Model identity, source, capabilities, and node placement remain configurable.
If the form blocks deployment, check the message under Node:
- No Tenstorrent runtime is installed: Ask your administrator to confirm that Tenstorrent support is enabled and the platform installation or upgrade has completed. The installed platform version must include the bundled runtime.
- More than one Tenstorrent runtime matches: Ask your administrator to configure one compatible runtime profile.
- The selected model preset requires a different accelerator: Select No preset (manual configuration) and check that your model supports Tenstorrent.
Model startup
The model can remain in Deploying while the runtime loads model weights and initializes the devices. This can take several minutes.
Check the deployment status and logs for progress. If the logs report a startup failure, ask your administrator to investigate before retrying the deployment.
Backend model ID
The Backend model ID field appears when you select a Tenstorrent node and use Pre-staged local path or a non-Hugging Face model URL.
Enter the canonical model identifier expected by the runtime. This is normally the
Hugging Face repository name, such as Qwen/Qwen3.6-27B, even when the weights are
stored locally. The warning disappears when you enter a value.
For a Hugging Face repository reference, the platform derives this identifier from the model URL, and the field stays hidden.
Backend model ID identifies the model for the serving runtime. It is separate
from API model id, which clients send in the OpenAI API's model field.
Deploying on an AMD GPU
Ask your platform administrator to complete the AMD prerequisites and enable AMD support.
Follow the Portal deployment procedure. Keep Preset set to
No preset (manual configuration). Select an AMD node and one or more GPUs
on that node. The platform selects the bundled cm-amd-vllm runtime.
Choose a model supported by the runtime and AMD hardware. When you select
multiple GPUs, the Portal updates --tensor-parallel-size under Arguments
to match the selected GPU count.
Advanced settings and GPU memory utilization remain configurable. Keep the default inference server image unless you have a compatible alternative built for ROCm and vLLM.
The bundled runtime's default arguments set a context limit of 4096 tokens.
A non-empty Arguments field replaces those defaults, including when the
Portal adds the parallelism argument. Include --max-model-len=4096 if you
want to retain that limit.
Leave GPU memory utilization blank to use the server default. The bundled AMD runtime defaults to 90%. For models sharing a GPU, aim for a combined total of 90% or less to leave memory headroom. The platform does not enforce this limit.
Changing an existing deployment
Open the deployment's settings to change its Node and GPUs. The Portal selects the compatible runtime when it can resolve the new placement. Changing the node or clearing the GPU selection clears GPU memory utilization. Enter the value again if you do not want to use the server default.
Starting a deployment or changing its running placement requires valid AMD placement. AMD availability checks do not prevent stopping a deployment or saving unrelated settings.
If the form cannot proceed
Check the message under Node:
- Select at least one AMD GPU from the current inventory: Select one or more GPUs from the current list.
- No AMD runtime is installed for this node: Ask your administrator to enable AMD support and confirm that the runtime is installed.
- More than one AMD runtime matches this node: Ask your administrator to configure one compatible runtime profile.
- The selected model preset requires a different accelerator: Select No preset (manual configuration) and check that the model supports AMD.
If the preset and runtime catalogue cannot be loaded, select Retry. The Portal keeps the current runtime selection. Retry before choosing a different runtime; this warning does not block every save.
vLLM Limitations
vLLM is an optimized inference engine for production environments. However, there are known limitations of vLLM to be aware of when choosing models. There is no universal engine that provides optimized inference for production environments for all possible types of machine learning models.
Supported models by vLLM are listed here: https://docs.vllm.ai/en/latest/models/supported_models.html
NB: Sometimes the very latest models from the latest release of vLLM can only be found on the release notes. https://github.com/vllm-project/vllm/releases
- vLLM generally supports autoregressive transformer models with text outputs.
- Diffusion-based models that generate images or videos are not supported.
- Multimodal inputs however are supported for many models.
- While vLLM supports most major model families, some niche models may not be supported.
- Not all major models are supported from day 0. However, model support usually comes within a few weeks.
- The most recent models often contain bugs that may affect performance. Usually these are worked on iteratively by the vLLM community, especially if the model demand is high. Generally it is recommended to reserve the most recent models from production environments until tested.