Configure a RAG endpoint
A RAG deployment grounds model answers in your own documents. Once it's deployed, you configure it from its page in the portal — which models it uses and who can access it. Its vector database is provisioned and managed for you; there's nothing to set up there.
Editors and Owners of a tenant create its RAG endpoints, and whoever creates one administers it. See Roles in a tenant.
See RAG for document and retrieval APIs, and Create and manage API keys for authentication.
Description
Agents and models read the RAG's description to decide when to search this knowledge base, so it should name the domain it covers and what is in it — for example: "Scientific knowledge base containing eleven papers on efficient large language model inference." Set it when you create the RAG, or later with Edit description at the top of the RAG's page.
Models
Under Settings, choose the models the RAG uses. Each can be any model on the platform — in-cluster or external:
- Embedding model — required; turns documents and queries into vectors.
- Generation model is only required for contextual embeddings, where it writes context for each chunk.
- Reranker model — optional; reorders retrieved chunks for relevance.
- OCR model — optional; reads text from images and scanned PDFs. Only models explicitly typed OCR can be selected (currently dots.OCR).
- Transcription model is optional and turns audio files into text during ingestion, so recordings can be indexed. Only models explicitly typed Transcription can be selected.
A model only works while it is running. A stopped model is still listed so you can see it exists, but it is marked (stopped) and cannot be selected — start it from the Models page first, then pick it here. Stopped models are hidden there until you select Show stopped models above the list. External models are always available.
When you create a RAG, each model is filled in from the platform default. A field is left empty instead when its platform default is no longer usable for that role — the model was deleted, is not available to you, is not of the role's type (only the OCR model field checks the type), or is stopped — and you can choose a model yourself. If every model listed for a required role is stopped, the form says so, and Create stays disabled until an embedding model is running.
On an existing RAG, a model that has stopped since it was configured stays selected but is marked (stopped). Start it again from the Models page, since a stopped model fails queries that reach it. For the generation, reranker and OCR roles you can pick another model instead.
The Embedding model cannot be changed after the RAG is created. Stored documents are vectors made by that model, and a different model cannot read them. Saving a different embedding model fails and nothing is changed. To use another embedding model, create a new RAG and add the documents to it.
The Generation model cannot be removed from a RAG that uses contextual embeddings. Setting it to None fails and nothing is changed. You can still choose a different generation model. See Indexing.
When the embedding model runs on the platform, the RAG copies its tokenizer files during startup. The tokenizer determines how text is split into tokens. If the tokenizer is unavailable, the RAG retries with a five-second delay until the copy succeeds. It cannot become ready or answer queries while waiting.
If the embedding model is stopped, a RAG that restarts after a settings change or an automatic update does not become ready. Start the embedding model from the Models page, and the RAG finishes starting on its own. Invalid or damaged tokenizer files cause startup to fail instead of retrying. External embedding models do not need this copy.
Every RAG also sends one short test request to its embedding model during startup to learn the size of its vectors. If the model does not answer, the RAG retries every five seconds and cannot become ready or answer queries until it does. This applies to external models too, so check that an external embedding model is reachable if a RAG does not finish starting.
The vector database holds at most 2000 numbers per vector. If the model's vectors are larger than that, a new RAG asks the model for vectors of 1024 numbers instead. If the model cannot return that size, the RAG does not become ready. Pick an embedding model with smaller vectors, or one that can return 1024.
A RAG that has not become ready within ten minutes shows Error instead of Deploying. A container that keeps crashing shows Error sooner. The RAG's page gives the reason, such as a pod that never reported ready or a container that keeps restarting. The RAG keeps retrying. Once the cause is fixed, for example by starting the embedding model again, it becomes Ready on its own without a restart.
A RAG has a memory limit. Indexing a very large file can take it over that limit, and the RAG then restarts and that upload fails. If this keeps happening, ask your platform operator to raise the RAG memory limit, as described in Size CPU and memory.
If you leave Reranker model empty, the RAG skips reranking. Choose a reranker model to rerank retrieved chunks.
To add BM25 keyword ranking next to vector search, turn on BM25 keyword search under Advanced settings when you
create the RAG, or set rag_config.bm25_search in the API. It cannot be changed after the RAG is created. UpdateRag
rejects that path in its update mask and keeps the stored value on a whole rag_config update.
A selected model is deleted
A RAG checks that every model it has selected still exists on the platform. A stopped model still exists, so stopping one does not trigger this check.
If the Embedding model is deleted, the RAG shows Error, even if it was answering searches until then. Without that model, it can neither index nor search documents.
If the Generation model, Reranker model or OCR model is deleted, the RAG shows Degraded and keeps answering searches. Requests that need the deleted model fail.
The RAG's page names the missing role and the API model id it points at. The text calls the OCR model the vision model.
To recover, deploy a model with the same API model id, or connect an external model with it. The RAG returns to its normal state on its own. For the embedding model it has to be the same model as before, see The embedding model is fixed once documents are indexed.
If the deleted model is the Generation model of a RAG that uses contextual embeddings, you cannot clear the field to get out of Degraded. Deploy a model with the same API model id, connect an external model with it, or choose another generation model.
Indexing
Two settings under Advanced settings on the create form decide how the RAG indexes documents. Neither can be changed after the RAG is created. Under Settings, the RAG's page shows both in the Ingestion group. To change one, create a new RAG and add the documents to it.
- Chunk size is the maximum number of tokens in each chunk. Leave it empty for 512 tokens, or for the embedding model's input limit if that is lower. A larger chunk size than that limit stops the RAG from starting. An external model's input limit is its context length, or 512 tokens if none is set. Enter it as a whole number of tokens, 1 or more.
- With Contextual embeddings on, the generation model writes short context for each chunk from its document before the chunk is embedded. This improves search but slows ingestion. It needs a generation model, so creating a RAG with contextual embeddings and no generation model fails. A RAG that uses it cannot have its generation model removed.
The RAG's page shows the values the RAG deployment was created with. RAG keeps the values its index was built with, so
editing chunkSize or contextualEmbeddings in spec.config afterwards does not change the index or the documents
already indexed.
In the API, set rag_config.chunk_size and rag_config.contextual_embeddings when you create the RAG. UpdateRag
rejects either path in its update mask, and keeps the stored values on a whole rag_config update.
Behavior
Also under Settings, tune how the RAG handles documents and answers searches. Each setting shows Enabled or Disabled beside its name. Select Edit to change them. They come in three groups.
The Ingestion group also shows Chunk size and Contextual embeddings. Both are set when the RAG is created, so Edit does not change them. Chunk size shows Default, or the number of tokens it was created with. See Indexing. The Search group also shows BM25 keyword search, which is set the same way.
Ingestion
- Enable PDF OCR by default when your PDFs contain tables or other complex layouts that the standard parser
may misread. This requires an OCR model. Portal uploads follow this setting. To override it for a single PDF,
set
use_ocrtotrueorfalsein the Files API upload.
Search
- Smart temporal search by default reads dates and time references in the search, such as "latest policy" or "what changed last month", and prefers the most time-relevant documents, unless the request asks for something else.
Groups (API only)
Groups are assigned to files only through the Files API and the Content API. Leave these settings off unless your application assigns groups.
- Delete files left without a group makes every upload name a group. Uploads without one are rejected, so the Files tab doesn't offer uploads while this is on. Removing a file from its last group deletes that file. Deleting a group deletes every uploaded file in the endpoint that is left with no group, including files uploaded before the setting was turned on. Files from data sources are never deleted this way.
- Require group for retrieval returns no results from the Context API when the request doesn't name a group.
The defaults suit most deployments. Adjust these only for specific needs.
Saving restarts the endpoint. The new settings apply after the restart, so wait until the endpoint is ready before you send requests.
Reranking defaults to 16 candidate chunks and batches of 16. These values can be overridden for a single query through the Context API.
Some endpoints show These settings are unavailable until this endpoint's configuration has been migrated. in place of the switches. Their description and any editable model selections can still be changed as usual. Configuration migration runs automatically during a platform upgrade. If this message remains after the upgrade, ask your platform operator to check the migration job. Restarting the endpoint does not run the migration.
Data sources
A data source connects the RAG to a store where you already keep your files. The RAG reads the files, indexes them, and reads the store again later to pick up changes.
Portal
Open the RAG's Files tab and select Add source.
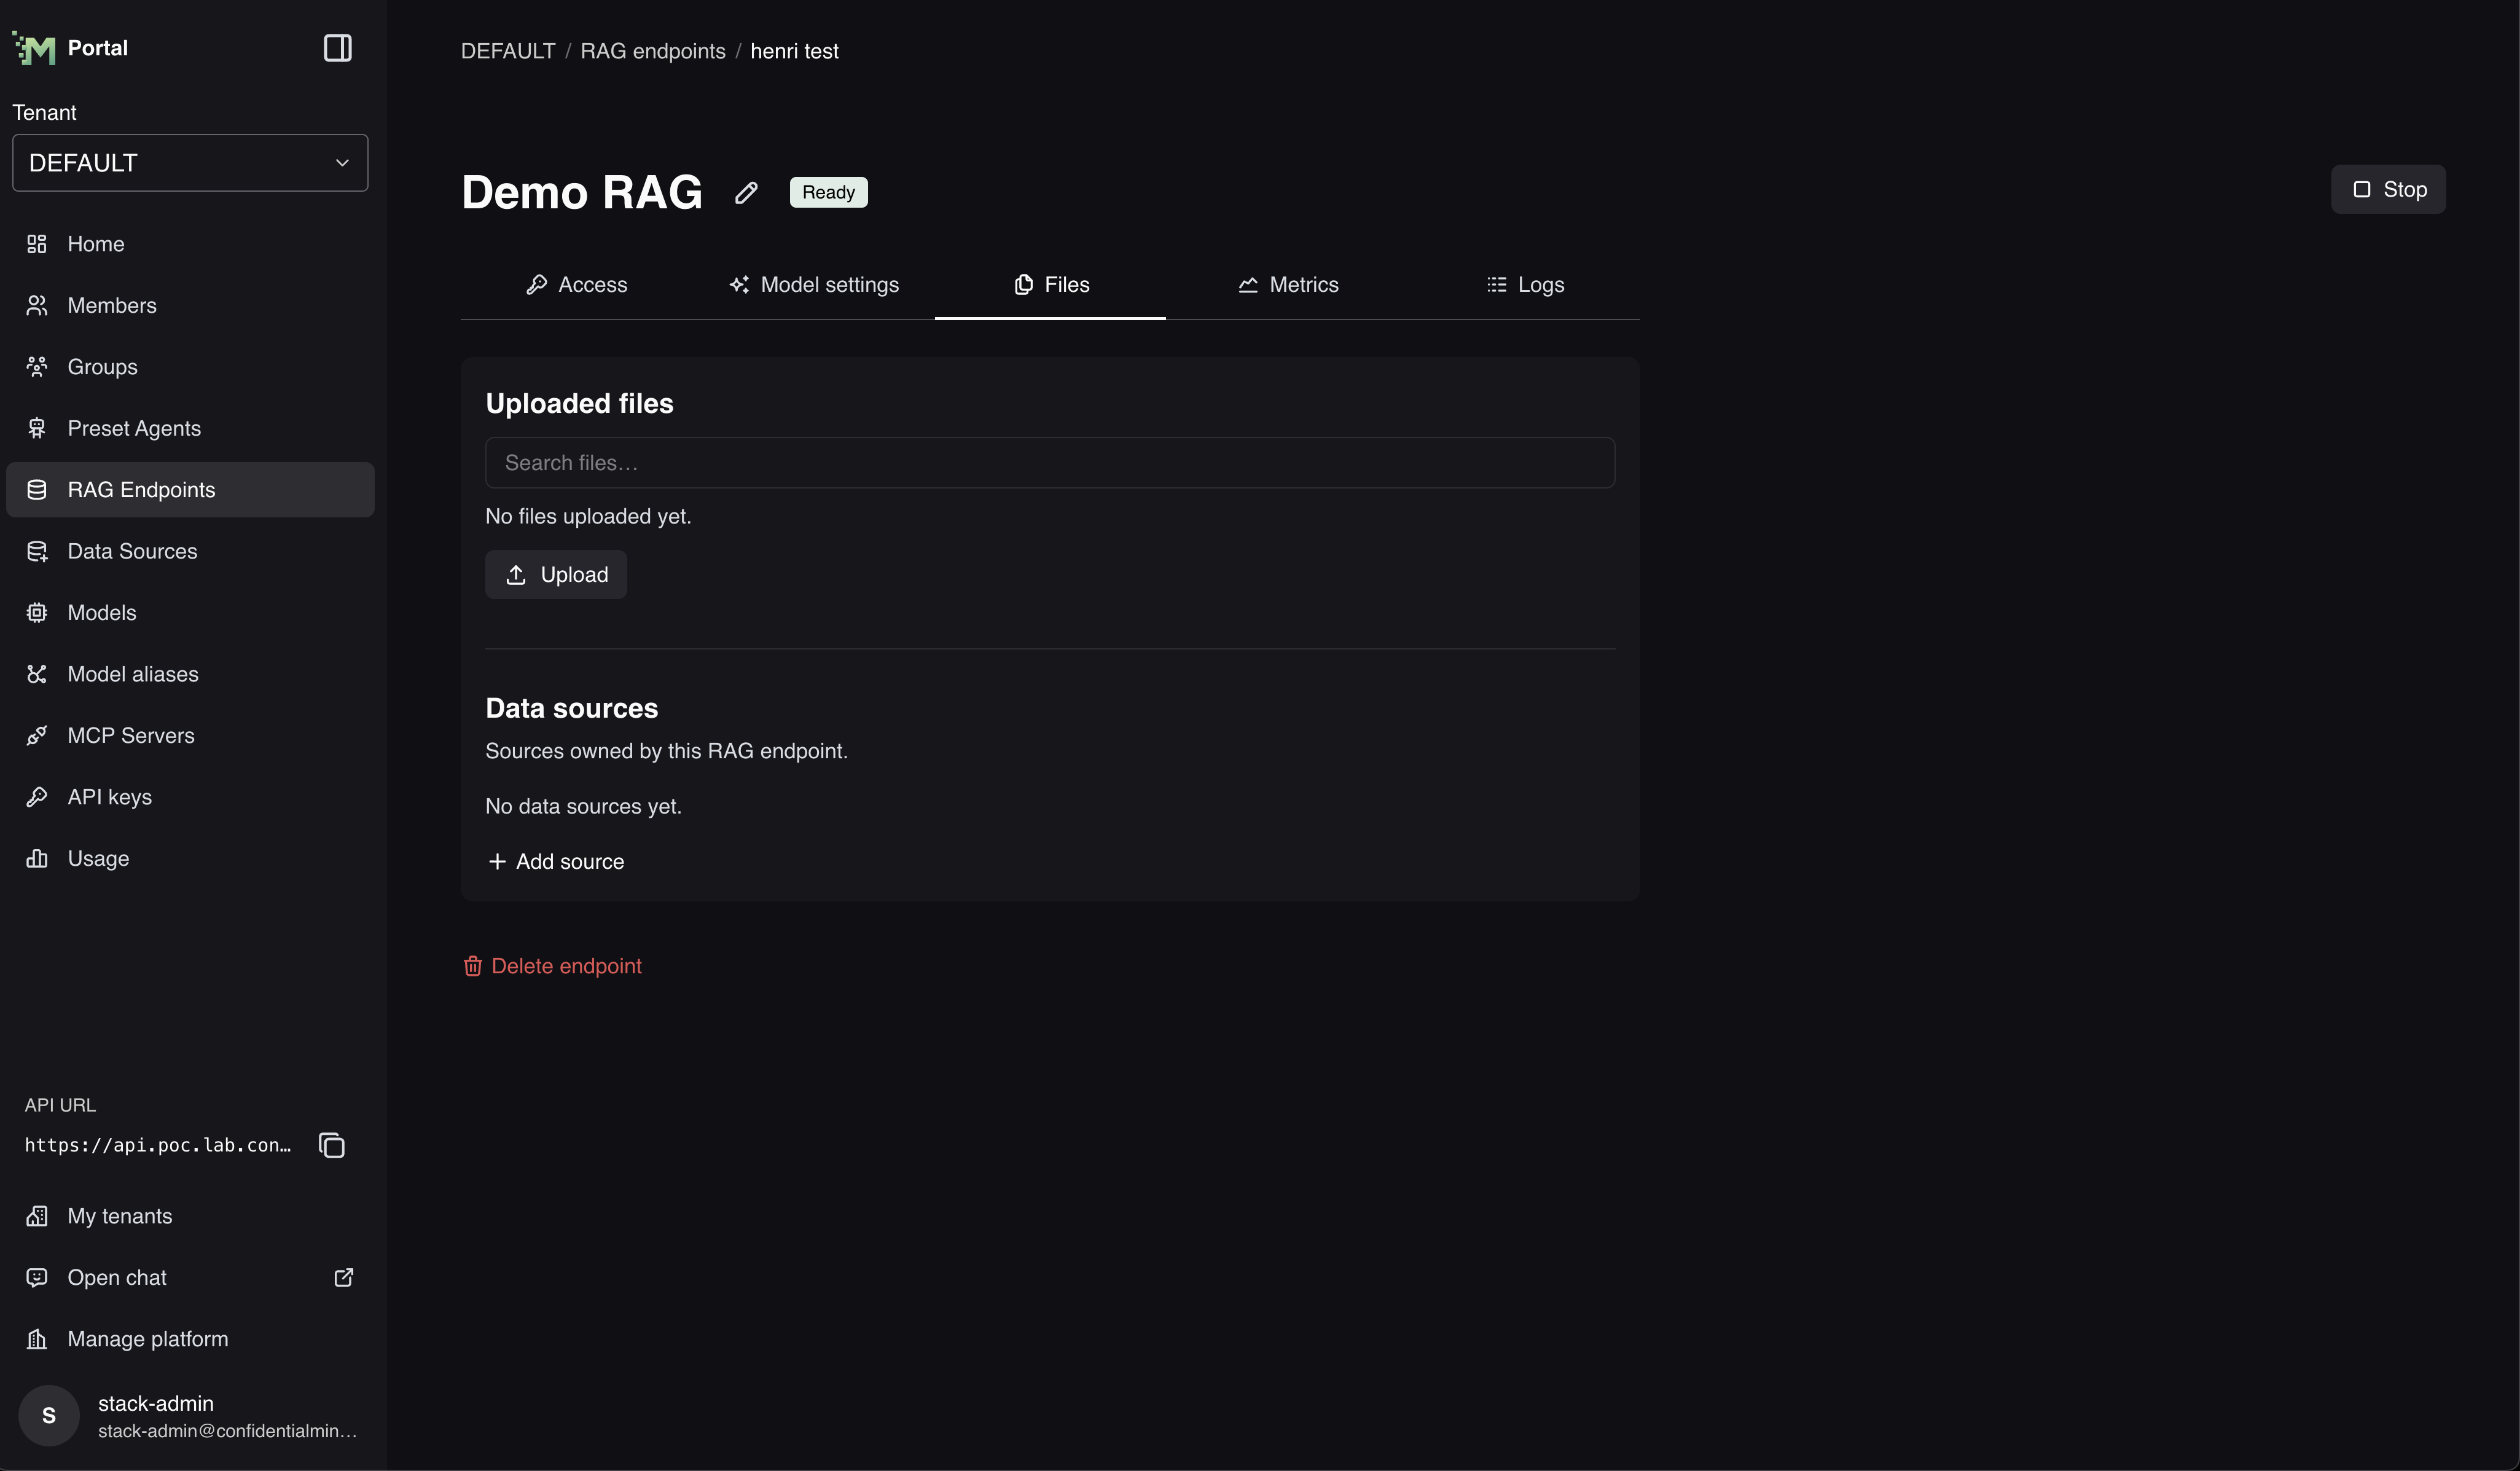
Choose the Provider: S3, Azure Blob Storage or an SMB file share. The fields change with your choice. See Connect a RAG data source for every field, how to prepare each store, and how the prefix and sync interval work.
Once the source is added, select it in the list to see its settings. An S3 source shows its Endpoint and Bucket; an Azure source shows its Account endpoint and Container.
Access
Portal
Open the RAG's Users tab to choose who can use the endpoint and who administers it. Administrators edit, start, stop and delete it, and manage its data sources. Users can read its configuration and data sources but can't make changes. They don't see a data source's sync Status, Files count, Last sync or Next sync. See Share a resource for the steps, including how to share with everyone in the tenant.
The RAG's Access tab holds its API URL and the calling examples.
Updates
A RAG keeps itself on the platform's recommended version automatically — nothing to do to stay current.
A platform upgrade can restart every RAG endpoint once, even when you changed nothing. The endpoints restart a few at a time, so some restart later than others. A RAG that uses a platform embedding model restarts one more time after that model first reports its context length, shortly after the model starts. An endpoint cannot answer queries while it restarts, so wait until it is Ready again.
A RAG that uses a platform embedding model splits text with that model's own tokenizer. When a RAG updates to a version that uses this tokenizer, previously indexed documents keep their existing chunks. The RAG does not index them again automatically, so new documents may be split differently. Upload a document again if you want it split with the model's tokenizer.
When a RAG updates to a version that no longer reads its RAG config file, it can search and split documents differently, so its results can change:
- An endpoint that ranked results by keywords alone now ranks them by meaning.
- An endpoint that has a Reranker model selected now reranks results, even if it did not rerank before.
- An endpoint that reranked 96 candidate chunks now reranks 16. A single request can ask for another number, see Context API.
- New documents are split into chunks of up to 512 tokens, and may be split differently than before. Documents that are already indexed keep their chunks. Upload a document again to split it the new way.
Endpoints that already used BM25 keyword ranking or contextual indexing keep those settings.
The embedding model is fixed once documents are indexed
The first time a RAG starts, it records which embedding model it uses and the size of its vectors. Every later start checks that record.
If a different model is put behind the same model name, or the model starts returning vectors of a different size, the RAG cannot become ready or answer queries. A running RAG is not affected until it restarts. Put the original embedding model back to let the RAG start again. To move to another embedding model, create a new RAG and add the documents to it.